My Worker Processes are Stalling!
Uploads or exports stuck on the on-screen log with no progress? Background jobs not completing? This guide walks through how to check and recover the worker layers involved. This guide covers VM deployments, where app (puma), resque (the background job workers), and nginx all run as OS processes supervised by god. Running Dradis Pro on Docker instead? See the Docker version of this guide.
After triggering an upload or export, the on-screen log should update continuously until Worker process completed appears. If it stalls with no progress, work through the sections below in order.
1. God Status
god is the process monitoring service that supervises all the other workers — if god itself isn't running, nothing else will be either, so this is always the first thing to check.
Run the following in the console as dradispro:
god statusThe expected output is:
cic-puma: up
dradispro-puma: up
nginx: up
resque:
  cic-resque-1: up
  dradispro-resque-1: up
If any process shows as down, or if the god command itself fails, try restarting god:
sudo /etc/init.d/god restartgod statusIf you've recently rebooted the instance and god didn't come back up cleanly, force it to reload its configuration:
god load /etc/god.d/dradispro-puma.godgod load /etc/god.d/cic-puma.godgod restartStill not right? Check the god log for more detail:
vi /var/log/god.logIf the god command returns command not found, your terminal session may not have loaded the correct environment. See the SSH Environment section of the instance troubleshooting guide.
2. Resque Workers
Resque workers handle background jobs — uploads, exports, migrations, and project tasks. A stuck resque process will cause uploads and exports to stall on the progress log even though the rest of the stack reports as up.
Quick restart
The first thing to try is a targeted resque restart via god:
god restart dradispro-resque-1If you're unsure which worker is stuck, or if the above doesn't resolve it, a full god restart will also cycle the resque workers:
god restartRetry the upload or export in the web app. If it's still stalling, move on to clearing the jobs queue.
Background Jobs: clearing the queue without the console
In Dradis v4.17.0 or later, click the cogwheel icon and select Background Jobs (or navigate to /pro/admin/jobs) to inspect and clear stuck jobs yourself, often without needing console access at all.
The Queues tab lists each queue (dradis_upload, dradis_export, dradis_project, dradis_mailers, dradis_send) with its pending job count. The Failed jobs tab (with a badge showing how many) lists anything that errored out.
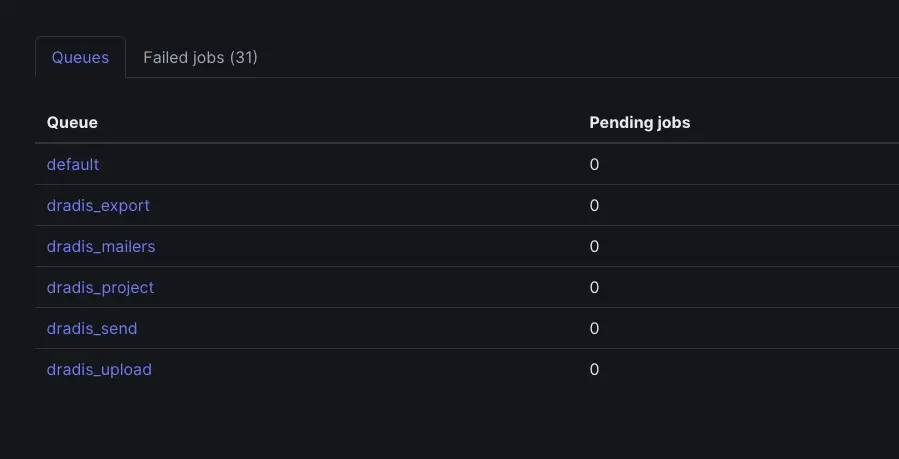
For a job that shows up under Failed jobs, open it and use:
- Retry — re-runs just that job. Try this first for a one-off failure (e.g. a transient error).
- Discard — permanently deletes that job. There's a confirmation prompt because this can't be undone; only use it for a job you don't need re-run.
To clear several at once, use Retry all or Discard all in the toolbar above the list (these apply to whatever filter is currently active, so narrow the list first if you only want to act on some of them).
When the UI isn't enough: Retry/Discard only act on jobs Resque already knows about. If a queue's Pending jobs count is stuck and not moving — and nothing is showing up under Failed jobs either — the resque worker process itself has likely hung, and there's no button here to restart it (the Workers tab isn't wired up for this app's setup). Go back to Quick restart above, or use the manual steps below if that doesn't clear it.
To kill stuck resque processes from the console, run the following as dradispro:
cd /opt/dradispro/dradispro/currentps aux | grep resqueA stuck worker will show output like this, with the job it is stuck on:
dradisp+ 12838 66.0  6.3 358416 130092 ?       Rl   20:08   0:00 resque-1.27.4:
Processing dradis_export since 1547687319 [ActiveJob::QueueAdapters::ResqueAdapter::JobWrapper]
Note down the process ID (the second column — 12838 in the example above) and kill it:
kill -9 12838Run the grep command again and repeat the kill -9 for any remaining stuck processes. You're done when all resque output shows Waiting rather than Processing:
dradisp+  8747  0.0  5.5 324868 114892 ?       Sl   Jan14   0:24 resque-1.27.4:
Waiting for dradis_export,dradis_upload,dradis_migrate,dradis_project
Once the workers are all in a waiting state, retry the upload or export in the web app.
Resque log files
If the restarts above resolve the stall but the problem keeps coming back, the resque logs are the place to look for the underlying cause. Check the following files as dradispro:
- /var/log/god/dradispro-resque-1.log
- /opt/dradispro/dradispro/shared/log/resque.log
vi /var/log/god/dradispro-resque-1.logAny recurring errors or exceptions in these logs are worth capturing and sending to the Support team.
3. Puma
Puma is the application server that serves Dradis. While resque handles background jobs, Puma needs to be healthy for the web interface to respond at all. Puma also serves the CIC (the Dradis Administrator Console), so there are two processes to check. A down Puma process can manifest as a 404 from nginx or a completely unresponsive UI even when the rest of the stack reports a clean status.
Check how many Puma master processes are running:
ps aux | grep "[p]uma master"You should see two processes — one for the CIC and one for Dradis. If either is missing, try starting it via god:
god start dradispro-pumaOr restart both:
god restart dradispro-pumagod restart cic-pumaPuma log files
If Puma is failing to start or keeps going down, the log files will usually tell you why. Check the following as dradispro:
Dradis:
- /var/log/god/dradispro-puma.log
- /opt/dradispro/dradispro/shared/log/puma.err.log
- /opt/dradispro/dradispro/shared/log/puma.out.log
- /opt/dradispro/dradispro/shared/log/production.log
CIC:
- /var/log/god/cic-puma.log
- /opt/dradispro/cic/shared/log/puma.err.log
- /opt/dradispro/cic/shared/log/puma.out.log
vi FILEPATHContact Us
Still stuck after working through the steps above? Gather the Support bundle from /setup/support in your instance and send it to our Support team — we'll give you a hand. If you aren't able to reach the endpoint above to download the support bundle, you can get it from a terminal session to Dradis with:
/opt/dradispro/bin/dp-support-bundle -o > /tmp/support-bundle.tar.gzNext help article: My tool output won't upload! →